All-Time Spotify Wrapped
Table of Contents
1. Overview
All-Time Spotify Wrapped is a containerized batch analytics pipeline that turns my Spotify listening activity into a year-round, queryable version of Spotify Wrapped. It combines scheduled Spotify Web API ingestion with a multi-year extended streaming history export, models the data into a star schema with dbt on DuckDB, validates it with ~70 dbt tests, and emits column-level lineage for every model to Marquez.
Reference: Builds on the ingestion approach from spotify-api by calbergs, extended with a DuckDB warehouse, dimensional models in dbt, a dbt test suite, and automated column-level lineage with OpenLineage and Marquez.
1-1. Problem & Goals
Spotify Wrapped is released once a year in a fixed format, and the Spotify Web API only returns the 50 most recently played tracks, so any listening history that isn't captured in time is lost. The pipeline is designed to:
- Capture plays before they fall out of the API window
- Merge ongoing API data with the historical export without duplicates
- Model the data for analysis with a dimensional (star) schema
- Make every metric traceable back to its source columns
- Run unattended, with alerts when something fails
1-2. Key Capabilities
- Scheduled Ingestion: Airflow runs the pipeline 8 times a day (hourly 9 AM–3 PM CST, plus 9 PM CST)
- Listening History: 33.5K+ plays (Mar 2022 – Sep 2026): 29.7K+ backfilled from the extended streaming history export and 3.8K+ captured through the API
- Dimensional Model: 15 dbt models across staging, marts, and analytics layers
- Data Quality: ~70 dbt tests on every run
- Data Lineage: Column-level lineage for every dbt model with OpenLineage and Marquez
- Alerting: Slack notifications on task retries and failures
- Open-Source Stack: Fully containerized with Docker Compose
2. Architecture
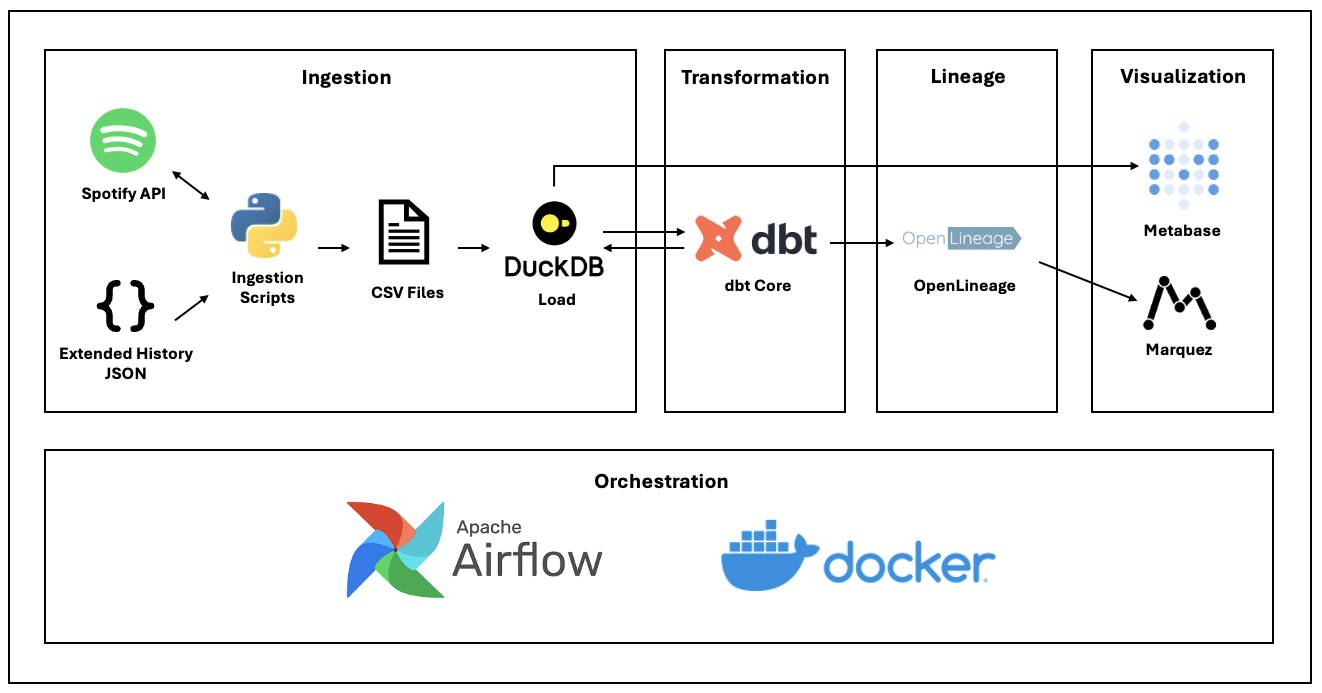
2-1. Technology Choices
- Apache Airflow: Orchestration with task dependencies, retries (2 attempts, 5 minutes apart), a single-slot pool that serializes DuckDB access, and failure/retry callbacks for alerting
- DuckDB: Embedded columnar OLAP engine; a single file with no server to operate, and fast analytical queries at this data size. The tradeoff is its single-writer file lock (see 3-1).
- dbt Core: SQL-based modeling, testing, and documentation, with
dbt_utilsfor surrogate keys - OpenLineage + Marquez: Open lineage standard with column-level granularity and a UI for exploring it
- Metabase (DuckDB driver): BI layer that queries DuckDB directly
- Docker Compose: One reproducible environment for Airflow, Metabase, and Marquez
2-2. Pipeline Design
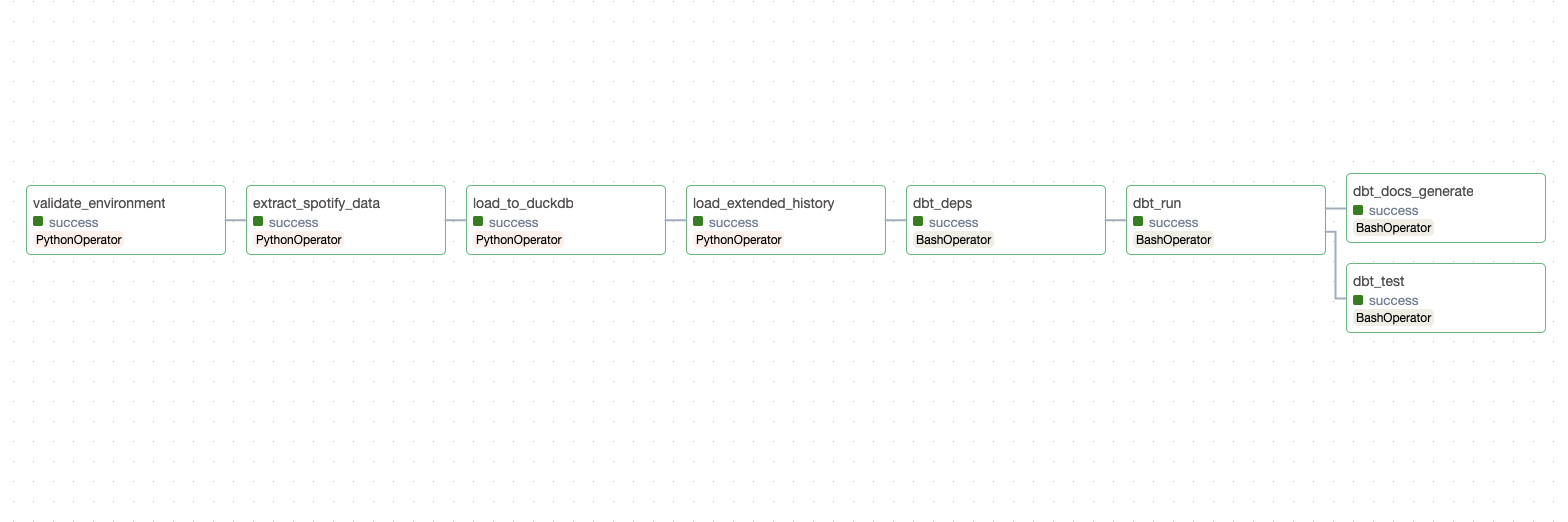
End-to-end view of the pipeline orchestrated by Apache Airflow:
1. Ingestion
- API Extraction: Pulls recently played tracks (the 50 most recent) along with artist and playlist details, and writes them to timestamped CSV files. Spotify credentials are managed through an Airflow Connection rather than a local token cache.
- Extended History: Spotify's extended streaming history export (JSON) backfills history the API can't return. Plays are deduplicated in the staging layer before they reach the fact table.
2. Loading
API loads into DuckDB raw tables are idempotent: plays are inserted with ON CONFLICT DO NOTHING, and artists, playlists, and playlist tracks are upserted, so reruns don't duplicate API data. File paths are validated before they are used in SQL to prevent injection.
3. Orchestration
Each run validates the environment, extracts from the API, loads API data, loads extended history, installs dbt dependencies, and runs dbt-ol run, followed by dbt test and dbt docs generate in parallel. All DuckDB tasks share a single-slot Airflow pool and the DAG is limited to one active run, so only one process writes to the database at a time.
4. Data Model (dbt)
- Staging (views): Deduplicates plays, parses timestamps, and filters out plays shorter than a minimum duration
- Marts (tables):
fct_listening_historywithdim_tracks,dim_artists,dim_albums, anddim_playlists - Analytics (tables): Daily top tracks and artists, hourly listening patterns, consecutive listening sessions, and playlist analysis
A surrogate play_id generated from track_id and played_at keeps API and export records from colliding. Audio-feature models and columns were removed after Spotify deprecated that part of its API.
5. Data Quality
64 schema tests (unique, not null, relationships) plus 6 custom tests covering duplicate plays, valid durations, positive play counts, sequential sessions, valid extended-history IDs, and a reconciliation test that checks fact-table play counts against dimension totals. Source freshness thresholds are configured (6-hour warning and 24-hour error on API plays), but they are not yet enforced in the DAG.
6. Lineage
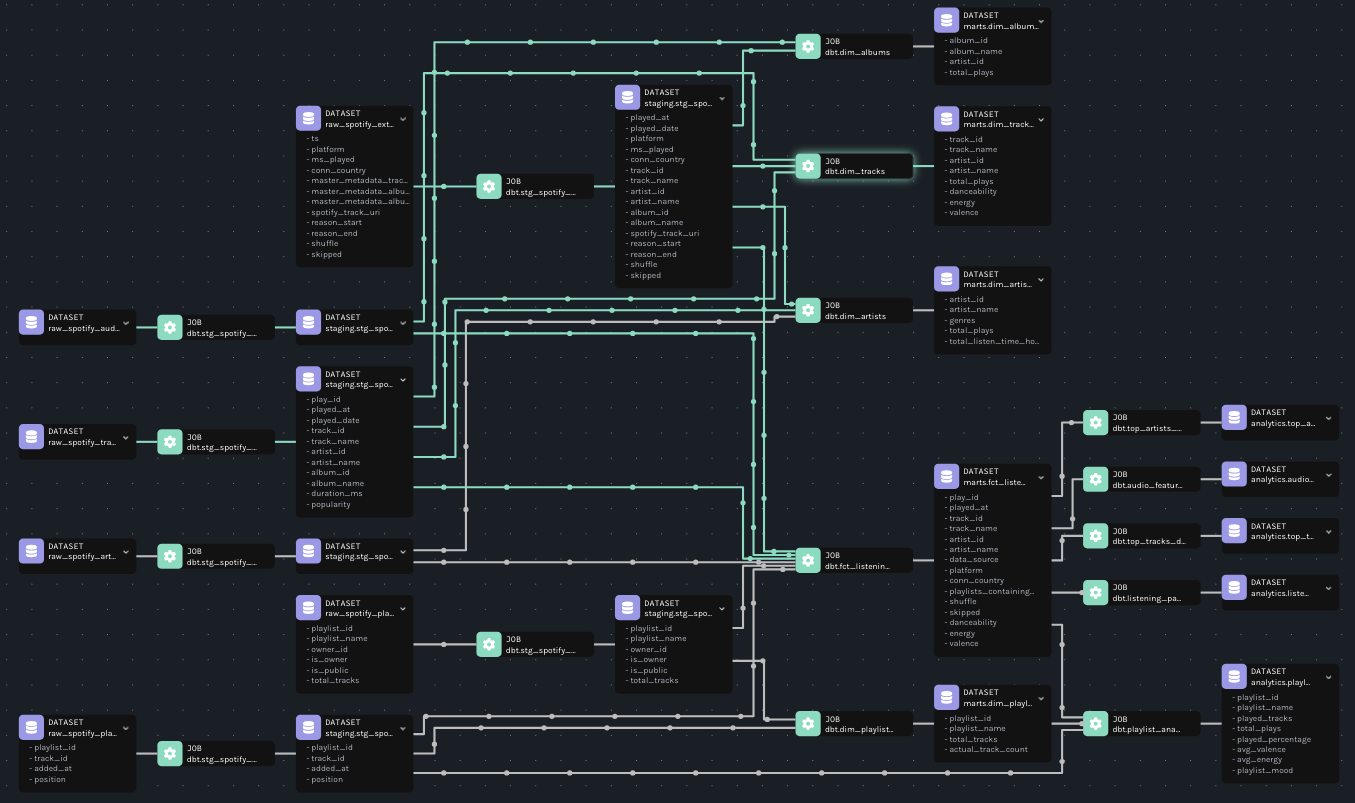
Running dbt through dbt-ol run emits OpenLineage events for every model, and Marquez shows column-level lineage from raw sources through staging and marts to the analytics tables.
7. Alerting
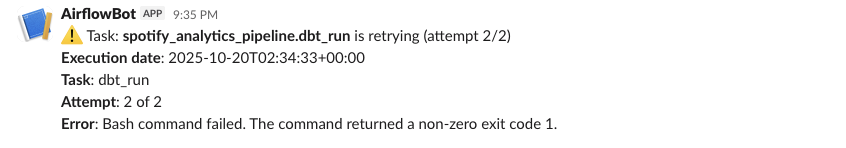
A retry callback posts to Slack on every retry attempt, and a failure callback fires once retries are exhausted, including links to the failed tasks and the error message.
3. Engineering Challenges
3-1. DuckDB Concurrency Locks (Open)
- Problem: DuckDB allows only one read-write process per database file. With Airflow tasks and Metabase connecting to the same file, the database locked and the containers had to be restarted.
- Root Cause: After serializing the pipeline's own access, Metabase's connection was identified as the remaining lock holder.
- What I Did: Serialized DuckDB tasks with a single-slot Airflow pool, one active DAG run, and sequential loaders; switched Metabase to a read-only connection and upgraded it from v0.51.3 to v0.56.9; simplified the loader's connection handling, removing 170 lines of code.
- Status & Tradeoff: Locks still recur while Metabase holds a connection. Separating the BI read path from the pipeline's write path is under evaluation. The underlying tradeoff is DuckDB's embedded, single-file simplicity versus concurrent multi-process access.
3-2. dbt + OpenLineage on DuckDB
- Problem:
dbt-ol runfailed with an error reporting that DuckDB was unsupported, so a custom Python script was used in the interim to emit lineage events manually. - Root Cause: An incompatible version of the
openlineage-dbtpackage. - What I Did: Pinned
openlineage-dbt==1.26.0;dbt-ol runnow emits lineage for all 15 models automatically, and the custom script was retired. - Tradeoff: The pinned version has to be revalidated on every dbt or OpenLineage upgrade.
3-3. Metabase and DuckDB Integration
- Problem: The official Metabase image couldn't read DuckDB, so data had to be synced to PostgreSQL just for BI, adding an extra pipeline step and a duplicate copy of the data.
- What I Did: Built a custom Metabase image with MotherDuck's DuckDB driver and removed the PostgreSQL sync. The image also runs Metabase as a non-root user through a
gosuentrypoint. - Tradeoff: Reading DuckDB directly simplified the architecture, but it is also what introduced the lock contention described in 3-1.
4. Results & Dashboard
- 33.5K+ plays modeled in
fct_listening_history(Mar 2022 – Sep 2026): 29.7K+ from the historical export and 3.8K+ captured through 8 scheduled runs a day - 15 dbt models and ~70 data-quality tests executed on every run
- Column-level lineage available for every model
Metabase Dashboard
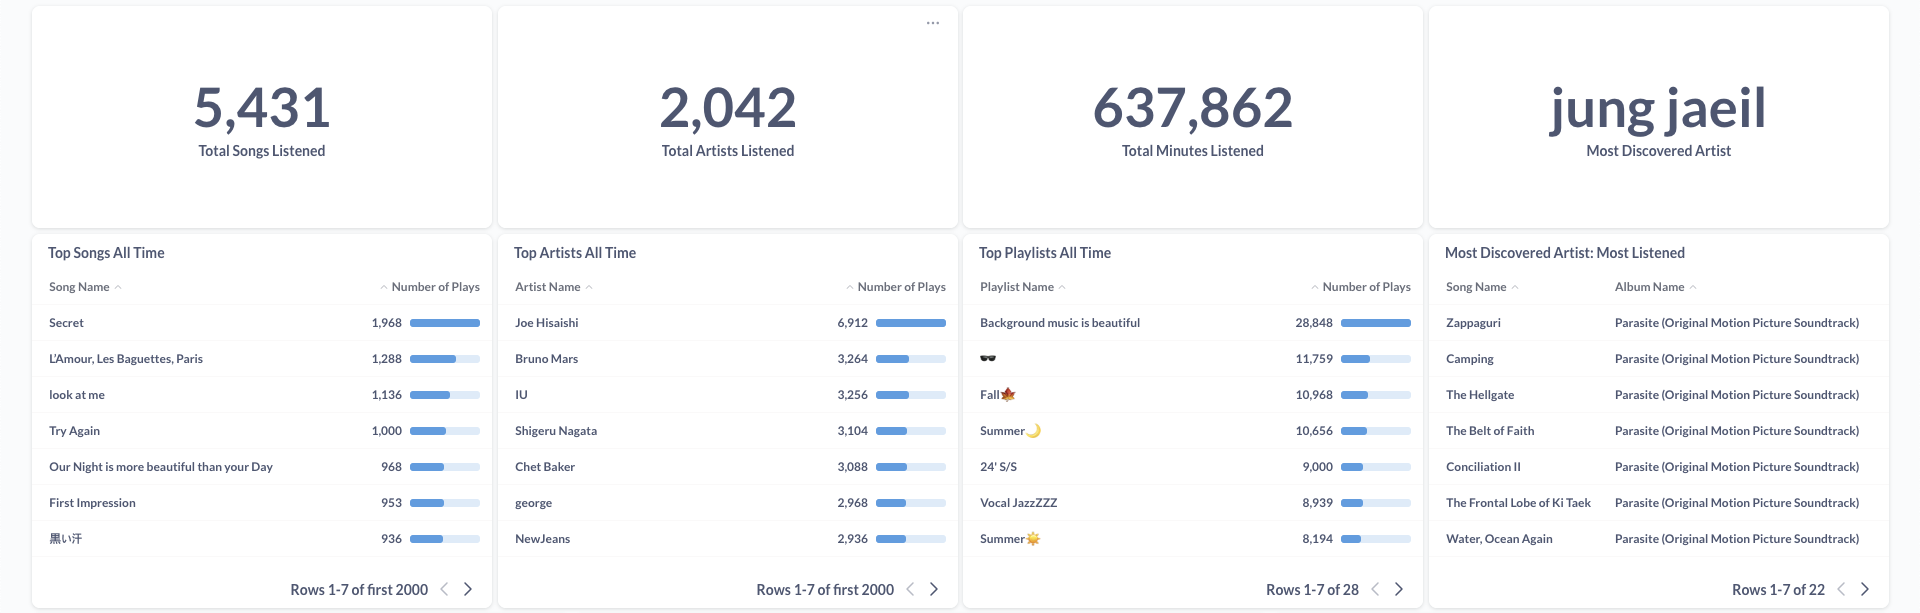
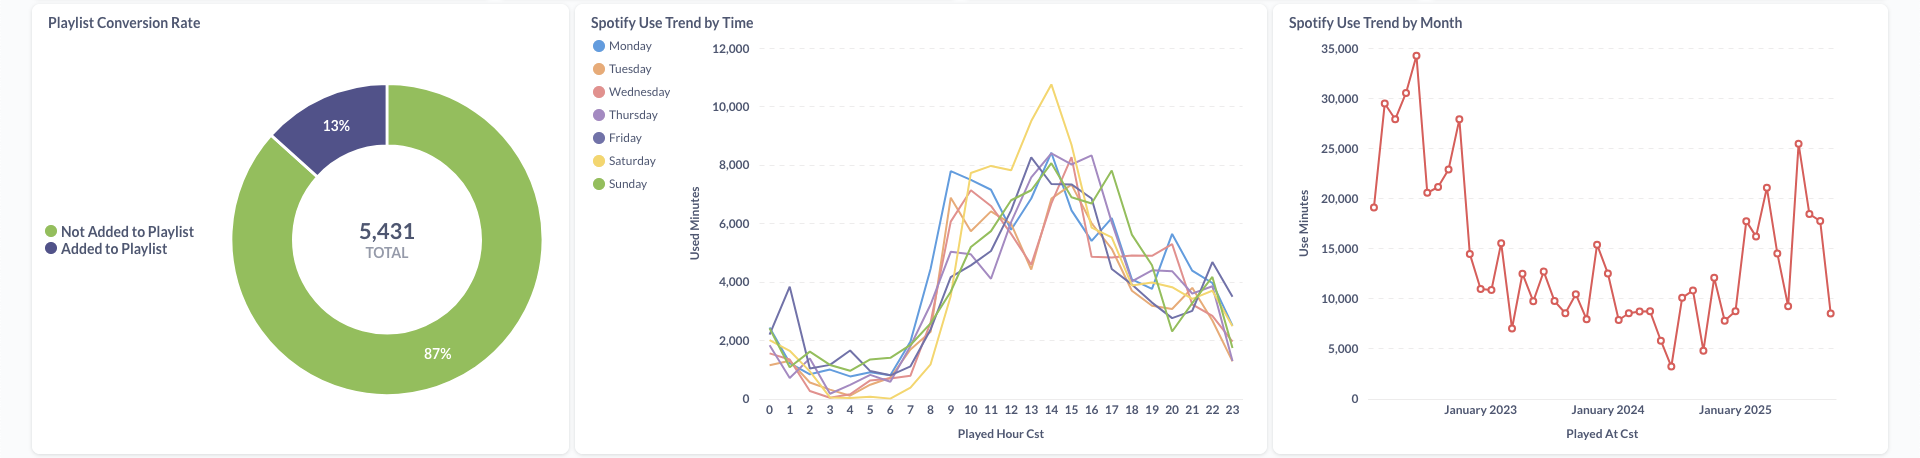
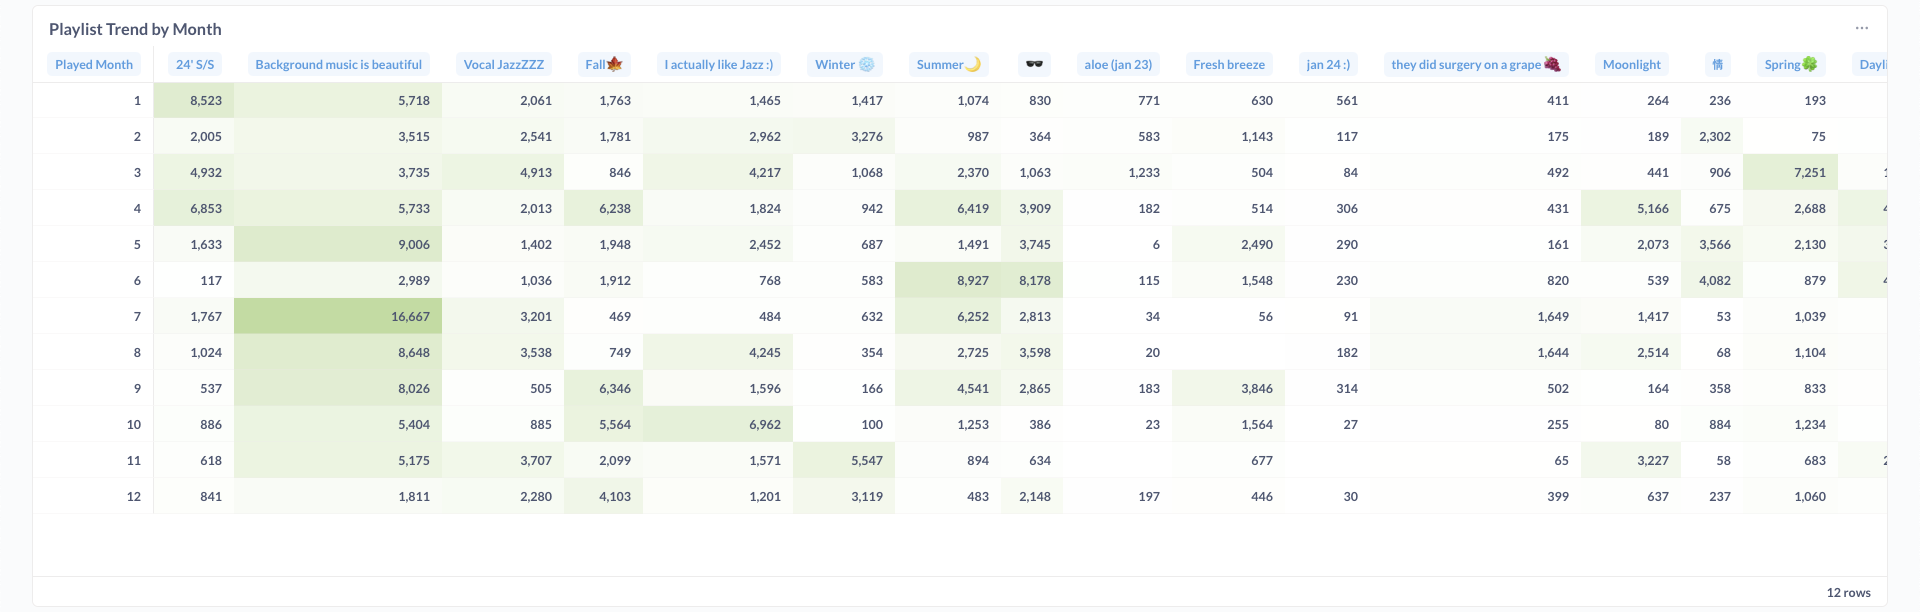
All-time and yearly listening trends by track, artist, and playlist:
5. Roadmap
- Resolve DuckDB lock contention by separating BI reads from pipeline writes
- Add
dbt source freshnessto the DAG so the configured thresholds are enforced - Make the extended history load idempotent; the raw table currently holds repeated loads of the export, which staging deduplicates
- Build a data-quality dashboard from dbt test results
- Support multiple users, each with their own listening history and analytics
- Publish interactive visualizations of the data on this website
At production scale, I would move storage to a warehouse or lakehouse with concurrent access, switch full table rebuilds to incremental dbt models, run dbt tests in CI on every pull request, and manage secrets in a dedicated secret manager.
Acknowledgments
- calbergs' spotify-api for the original ingestion approach
- Spotify for the Web API
- Open-source communities behind Airflow, dbt, DuckDB, OpenLineage, and Marquez
Spotify API usage complies with Spotify's Developer Terms.